2009年10月29日星期四

grub iso

同样的,启动ISO也是
map和map --mem
绝对路径和相对路径

title  8, Boot ISO
find --set-root /ggho/grub/gghost.img
map  --mem /test.iso (0xff)
map --hook
chainloader (0xff)

title  9, Boot ISO
map  --mem (hd0,4)/test.iso (0xff)
map --hook
chainloader (0xff)

title  10, Boot ISO
find --set-root /ggho/grub/gghost.img
map  /test.iso (0xff)
map --hook
chainloader (0xff)

2009年10月25日星期日

FreeRange story - “开源”之战的意义何在

FreeRange user liu monokeroz wanted you to see this:

""开源"之战的意义何在"

卫报中文版 写道 "多年来,开源运动和微软之间的斗争几乎成了一场宗教战争。双方的火力越来越猛--从微软的老板史蒂夫fffffc2fffffb7鲍尔默称开源运动是"一种癌症",到Linux创始人李纳斯fffffc2fffffb7托沃兹暗示,他可以不费吹灰之力地"摧毁微软"。最近,Lotus创始人、Mozilla基金会会长米奇fffffc2fffffb7卡普尔宣称"微软同开源软件的战争已经结束,因为微软及其追随者的抵抗不堪一击"。针对火狐所取得的成就,他表示,"我告诉人们Mozilla和Firefox的历史是这样的,它永远不应该作为一个'可能的'例子。开源码的成就在于它是网络后端,是无形部分,作为用户你看不到的部分。"另外,他还就开源运动的形成以及开源与网络的关系发表了看法。"

Solidot

FreeRange WebReader - bringing the Internet to your mobile phone like never before!

Reading this on your Windows Smartphone, Palm or Blackberry? Try it now by clicking http://mwap.at

2009年10月21日星期三

FreeRange story - View Your Website’s Visitors’ IP Address & Keep Statistics

FreeRange user liu monokeroz wanted you to see this:

"View Your Website's Visitors' IP Address & Keep Statistics"

There's no debate whether or not our online activities are tracked, they most surely are. It's not even a single party that keeps the score; your ISP, website owners, advertisers and NSA know the reason you switched to Private Browsing Mode yesterday at 22:12. If the cool kids are doing it, why shouldn't you? Here's how you can get to 'know' your website's visitors IP address.

The first thing you want to do is go about creating an account over at Google Analytics . Why would I want to do that, you ask? Well, in my own experience, the service provides a tremendous amount of data, has a great user interface, is easy to install on any website, and, more importantly, is completely free of charge. It's undoubtedly the easiest, cheapest and fast way of getting your visitors' information, including their IP address or hostname.

If you already use any of the Google services, you can easily sign in with your existing credentials. The process of setting up your website with Google couldn't be easier. You will be prompted to create a profile. A profile is basically a metaphor for a folder, where you can keep track of various aspects of your websites' traffic. Each different domain will have its own separate profile. Select 'Add Profile for a new domain' and enter your domain's address and timezone.

The next page will generate a bit of code that you'll have to insert in the header or footer of your website's template. You have to do this because youfffffc2fffffa0 want to keep track of visitors across your website, not just the homepage. This way, no matter where the user navigates to (eg. mysite.com/secondpage), you will know about the total time spent, the pageview/unique visitor ratio and exit funnels.

How you add the code to your website varies dramatically – and requires the knowledge to manually access and edit your theme files. You probably set your own website up, so you must know how to do this. If you don't know how, don't panic, and instead search Google for '[service type] + edit theme OR Google Analytics '. For example, 'Wordpress edit theme Google Analytics'. There are plenty of guides out there that will show you how to add this bit of code.

In the latest version of the self-hosted Wordpress, I only need to click on 'Appearance' in the sidebar, 'Editor' and choose from the right side list 'footer.php'. As a golden rule, insert the code before the last '</body></html>' tags. They've also got a lot of support material over at the help page , which you might want to check out if in doubt.

Twenty-four hours later and you've got the first taste of website statistics. Be prepared to spend the rest of the evening looking at various graphs of source locations, connection speed, ISP, browser capabilities, operating systems, browsers, time on site and more. After that, the only problem that could arise is that you'll wish you could install a tracking code in your girlfriend, in order to be plot the 'visitor loyalty' chart.

If you want to view individual IP addresses of your website's visitors you need to click on Visitors>Network Properties>Hostnames, from the right sidebar, as illustrated in the screenshot above. There you will see a list of IP addresses and how many times each has visited the website. This can prove useful if your site is being attacked (defaced , DDOS -ed, etc.), as you can determine who your attacker is, or at least his proxy .

More views and information is accessible through the sidebar on the right: Visitors, Traffic Sources, Content and Goals. They're pretty much self explanatory. The Visitors tab will contain information about – you've guessed it, the people who accessed your site. Traffic sources will identify who sent you traffic, be it a search engine, a referral or just organic. The Content tab will dutifully tell you how each page is doing when it comes to attracting eyeballs. Finally, Goals is used by e-commerce folks and companies to measure conversions, a fancy word for a sell.

You should definitely spare a minute to check out the quite extensive page of articles about blogging tools .

Did you like the post? Please do share your thoughts in the comments section!

New on Twitter ? Now you can follow MakeUseOf on Twitter too.
Related posts

• Su.pr – An Extraordinary URL Shortener from StumbleUpon (13)
• Is Your Wireless Network Safe? (9)
• How to Trace an IP Address to a PC & How to Find Your Own (24)
• Google Analytics Tips You Should Know About (11)
• Free Traffic Analytics Tools you Should Know About (13)

Makeuseof

FreeRange WebReader - bringing the Internet to your mobile phone like never before!

Reading this on your Windows Smartphone, Palm or Blackberry? Try it now by clicking http://mwap.at

2009年10月19日星期一

SQLite

SQLite

From Wikipedia, the free encyclopedia

Jump to: navigation, search
SQLite Logo 4.png
Developer(s) D. Richard Hipp
Initial release August 2000 (2000-08)
Stable release 3.6.19 / 2009-10-14; 6 days ago
Written in C
Operating system Cross-platform
Size ~225 kB
Type RDBMS (embedded)
License Public domain
Website http://sqlite.org/

SQLite is an almost ACID-compliant embedded relational database management system contained in a relatively small (~225 kB)[1] C programming library. The source code for SQLite is in the public domain.

The SQLite engine is not a standalone process with which the application program communicates. Instead, the SQLite library is linked in and thus becomes an integral part of the application program. The library can also be called dynamically. The entire database (definitions, tables, indices, and the data itself) is stored as a single cross-platform file on a host machine.

Contents

[hide]

[edit] Design

Unlike client-server database management systems, the SQLite engine is not a standalone process with which the application program communicates. Instead, the SQLite library is linked in and thus becomes an integral part of the application program. The library can also be called dynamically. The application program uses SQLite's functionality through simple function calls, which reduces latency in database access as function calls within a single process are more efficient than inter-process communication. The entire database (definitions, tables, indices, and the data itself) is stored as a single cross-platform file on a host machine. This simple design is achieved by locking the entire database file at the beginning of a transaction.

[edit] History

SQLite was first designed by D. Richard Hipp in the Spring of 2000 while working for General Dynamics on contract with the United States Navy.[2] Hipp was designing software used on board guided missile destroyer ships, which were originally based on HP-UX with an IBM Informix database back-end. The design goals of SQLite were to allow the program to be operated without database installation or administration. In August 2000, version 1.0 of SQLite was released, based on gdbm (GNU Database Manager). SQLite 2.0 replaced gdbm with a custom B-tree implementation, adding support for transactions. SQLite 3.0, partially funded by America Online, added internationalization, manifest typing, and other major improvements.

[edit] Features

SQLite implements most of the SQL-92 standard for SQL but it lacks some features. For example it has partial support for triggers, and it can't write to views. While it supports complex queries, it still has limited ALTER TABLE support, as it can't modify or delete columns.[3]

SQLite uses an unusual type system for an SQL-compatible DBMS. Instead of assigning a type to a column as in most SQL database systems, types are assigned to individual values; in language terms it is dynamically typed. Moreover, it is weakly typed in some of the same ways that Perl is: one can insert a string into an integer column (although SQLite will try to convert the string to an integer first, if the column's preferred type is integer). This adds flexibility to columns, especially when bound to a dynamically typed scripting language. However, the technique is not portable to other SQL databases. The inability to have the domain integrity coming from statically typed columns, as in typical databases, is a common criticism. The SQLite web site describes a "strict affinity" mode, but this feature has not yet been added.[4] However, it can be implemented with constraints like CHECK(typeof(x)='integer').[2]

Several computer processes or threads may access the same database without problems. Several read accesses can be satisfied in parallel. A write access can only be satisfied if no other accesses are currently being serviced, otherwise the write access fails with an error code (or can automatically be retried until a configurable timeout expires). This concurrent access situation would change when dealing with temporary tables.

A standalone program called sqlite3 is provided which can be used to create a database, define tables within it, insert and change rows, run queries and manage an SQLite database file. This program is a single executable file on the host machine. It also serves as an example for writing applications that use the SQLite library.

SQLite also has bindings for a large number of programming languages, including BASIC, C, C++, Clipper, Common Lisp, Java, C#, Visual Basic, Delphi, Curl, Lua, Tcl, REBOL, R, PHP, Perl, Ruby, Objective-C (on Mac OS X), Python, newLisp, Haskell, OCaml, Smalltalk and Scheme. There is also a COM (ActiveX) wrapper making SQLite accessible on Windows to scripted languages such as Javascript and VBScript. This adds database capabilities to HTML Applications (HTA).[5]

SQLite has automated regression testing prior to each release.[6] Over 2 million tests are run as part of a release's verification. Starting with the August 10, 2009 release of SQLite 3.6.17, SQLite releases have 100% branch test coverage, one of the components of code coverage.

[edit] ACID compliance

ACID consistency means that only valid data can be written to the database. If a transaction is executed that violates the database's consistency rules, the entire transaction should be rolled back and the database restored to a state consistent with those rules. SQLite by design doesn't enforce integrity constraints on data written to the database so it is not strictly ACID-compliant. One could insert eg. a string to an integer column, too long string or an invalid date into a database with no error. The consistency of data inserted into a database must be verified by an application.[original research?]

[edit] Development

SQLite development is hosted on Fossil, a distributed version control system which is itself built upon an SQLite database.[7]

[edit] See also

[edit] References

  1. ^ "Distinctive Features Of SQLite". SQLite. March 3, 2008. http://www.sqlite.org/different.html. Retrieved July 9, 2009. 
  2. ^ a b Owens, Michael (2006). The Definitive Guide to SQLite. Apress. doi:10.1007/978-1-4302-0172-4_1. ISBN 978-1-59059-673-9. 
  3. ^ "SQL Features That SQLite Does Not Implement". SQLite. January 1, 2009. http://www.sqlite.org/omitted.html. Retrieved October 14, 2009. 
  4. ^ "Frequently Asked Questions". SQLite. January 26, 2009. http://www.sqlite.org/faq.html. Retrieved February 7, 2009. 
  5. ^ "sqlite — Sqlite Wrappers". SQLite. February 7, 2009. http://www.sqlite.org/cvstrac/wiki?p=SqliteWrappers. Retrieved February 7, 2009. 
  6. ^ "How SQLite Is Tested". SQLite. http://www.sqlite.org/testing.html. Retrieved September 12, 2009. 
  7. ^ "Fossil: Fossil Performance". Fossil-scm.org. 2009-08-23. http://www.fossil-scm.org/index.html/doc/tip/www/stats.wiki. Retrieved 2009-09-12. 

[edit] Further reading

  • Newman, Chris (November 9, 2004), SQLite (Developer's Library) (First ed.), Sams, p. 336, ISBN 067232685X 

[edit] External links

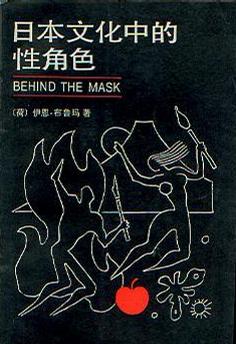
日本文化中的性角色

《日本文化中的性角色》(Behind the Mask)中译本,扫描版[PDF]

状态: 精华资源
第二轮版主公开招募开始了!
摘要:
发行时间: 1989年04月
语言: 简体中文
时间: 8小时前 发布 | 8小时前 更新
分类: 资料   电子图书  
统计:4019次 浏览 | 20次 收藏
收藏: fav  分享给好友
相关: 分享到开心网  分享到校内  收藏到QQ书签  订阅本资源RSS更新  美味书签  subtitle
中文名: 日本文化中的性角色
英文名: Behind the Mask
资源格式: PDF
版本: 中译本,扫描版
发行时间: 1989年04月
地区: 大陆
语言: 简体中文
简介: 

IPB Image

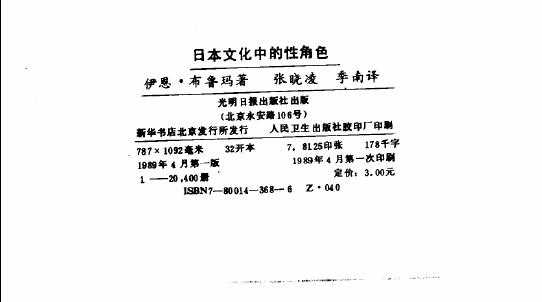
◎译  名 日本文化中的性角色
◎原  名 Behind the Mask
◎作  者 [荷]伊恩・布鲁玛
◎译  者 张晓凌 季南
◎出版时间 1989
◎国  家 中国
◎类  别 人文社科-文化
◎版  本 扫描版
◎语  言 简体中文
◎文件格式 PDF
◎文件大小 5.8MB
◎页  码 242页
◎ISBN 9787800143687

内容介绍:

  本书前半部分是关于女人,后半部分是关于男人。女人大致分担她们在众多社会里担当的两种传统角色:母亲和妓女。她们在日本都很重要。虽然这两种角色的区分在日本社会比在其他任何地方都更严格,它们之间仍有某些相同之处。它们无疑是按照男人们的欲望塑造的。
  在本书的前后两部分之间夹有一章关于第三种性,即女扮男装和男扮女装的人。这种异性扮演在日本戏剧中仍然举足轻重。正式在这个朦胧世界里,性的角色被划分得最清楚。
  本书后半部分以很大篇幅描写日本歹徒(日文:亚枯杂)的传统世界。这是因为这个幻想世界几乎成了日本社会绝妙的缩影。

内容截图:

IPB Image
IPB Image


目录: 

序言
第一章 神的镜子
第二章 永存的母亲
第三章 神圣的婚姻
第四章 魔鬼女人
第五章 活艺术品
第六章 妓女的艺术
第七章 第三种性
第八章 坚忍派
第九章 忠实的侍从
第十章 歹徒与虚无主义者
第十一章 取笑父亲
第十二章 旅途中的流浪汉
第十三章 结论:一个文雅的民族
附:注解及参考书目

Kepler (software)

Kepler (software)

From Wikipedia, the free encyclopedia

Jump to: navigation, search
Kepler
Kepler Project logo.gif
Developer(s) Kepler Project team
Initial release July 2005 (2005-07)
Stable release 1.1.1 / 2009-03-11; 7 months ago
Operating system Cross-platform
Type Web application framework
License MIT License
Website http://keplerproject.org

Kepler is a free software project written in Lua that provides a portable, extensible website development platform. Current stable release is Kepler 1.1.1, for Lua 5.1. Kepler works on Windows and most variants of Unix.

The platform was designed to work with a number of web serving environments, called "launchers" in Kepler terminology. Kepler includes launchers for Apache (mod lua), FastCGI, CGI, ISAPI as well as a native web server written in pure Lua, called Xavante [1].

[edit] Kepler Modules

Kepler also provides the following modules:

  • CGILua - tool for creating dynamic Web pages and manipulating input data from Web forms, providing a CGI-like programming paradigm for different launchers such as Xavante and mod_lua
  • LuaSQL - an interface from Lua to a DBMS, enabling Lua programs to connect to ODBC, ADO, Oracle, MySQL, SQLite and PostgreSQL databases
  • Copas - a coroutine-based dispatcher, used by Xavante
  • LuaFileSystem - a library of file manipulation routines complementing Lua's basic set.
  • Rings - a library for creating isolated Lua execution environments from within Lua.
  • LuaExpat - an interface to the XML processing library Expat.
  • LuaLogging - a simple logging API
  • LuaZip - library for reading inside ZIP files
  • MD5 - basic cryptographic library, providing a digest function and a crypt/decrypt pair.

[edit] Webapps on Kepler

Sputnik is a wiki with embedded Kepler.

[edit] External links


Catalyst (software)

Catalyst (software)

From Wikipedia, the free encyclopedia

Jump to: navigation, search
Catalyst logo3.png
Original author(s) Sebastian Riedel
Stable release 5.80007 / 2009-06-30; 3 months ago
Written in Perl
Type Web application framework
License PAL and GPL
Website www.catalystframework.org

Catalyst is an open source web application framework written in Perl, that closely follows the model-view-controller (MVC) architecture, and supports a number of experimental web patterns. It's heavily inspired by such frameworks as Ruby on Rails, Maypole, and Spring.

Catalyst is primarily distributed through the CPAN, which is the official distribution channel for Perl libraries and applications.

Contents

[hide]

[edit] History

Catalyst's first development release took place on 2005-01-28. The first official version hit CPAN on 2005-02-16[1]. As of 2009-06-01, Catalyst has 85 registered contributors[2].

[edit] Philosophy

Catalyst is based on a "don't repeat yourself" (DRY) principle, which means that definitions should only have to be made once.

Catalyst can be used with automatic class loading from the database through one of the many loader modules, thus requiring no code for the database layer. But, if you require the flexibility of manually doing everything, it's also an option. Another guiding principle of Catalyst is flexibility.

Catalyst promotes the re-use of existing Perl modules that already handle common web application concerns well.

  • The Model part is handled through DBIx::Class, Plucene, Net::LDAP and other model classes.
  • The View layer is usually handled by Template Toolkit, Mason, or HTML::Template, among others.
  • The Controller layer, of course, is written by each application author. Large chunks of Controller functionality can usually be deferred to one of the many Catalyst plugins (e.g., Catalyst::Plugin::FormValidator, Catalyst::Plugin::Prototype, Catalyst::Plugin::Account::AutoDiscovery, etc.).
  • Finally, Catalyst offers a set of helpers to simplify flow control and mapping URLs to controller methods.

Catalyst has a large selection of plugins. For example, it has JavaScript generation for Ajax and RIAs using the Catalyst::Plugin::Prototype module (prototype is an Ajax framework).

[edit] Web server support

For development and testing, Catalyst has a built-in simple HTTP server. For production use, Apache, lighttpd or Nginx with FastCGI or mod_perl support is recommended, but any web server with CGI or FastCGI support will work. On Apache, mod_perl can help with performance considerably, though its use might be an issue because it can be unsafe to share multiple applications under mod_perl.

Since early 2008, Catalyst applications can also be deployed using the HTTP::Prefork engine which provides for the deployment of high performance Catalyst applications without a separate web server.

[edit] Database support

Catalyst can run using any database supported by Perl's DBI (this means almost anything, even a CSV file), but a proper RDBMS or ODBMS is recommended. The database access is entirely abstracted from the programmer's point of view and Catalyst, through one of its model classes, handles access to all databases automatically – though, if needed, using direct SQL queries is possible. This enables database-neutrality, application portability over different database systems, and usability of pre-existing databases for Catalyst application development as much as possible, though due to different feature sets of the RDBMSes, it is not completely guaranteed by the framework alone. Several different RDBMS systems are supported, including MySQL, PostgreSQL, SQLite, IBM DB2, Oracle and Microsoft SQL Server. For ODBMSes, there is explicit support for KiokuDB via Catalyst::Model::KiokuDB. The Model abstraction allows databases of any nature to be accessed via Catalyst::Model::Adaptor.

A lot of Catalyst-based projects use DBIx::Class as the ORM layer, which provides further abstraction of SQL queries, using a resultset-based API with transparent (and efficient) support for arbitrary joins and other features.

[edit] See also

[edit] References

[edit] External links